Vertical Search Engine
The search engine extracts institutional research metadata, ranks keyword queries with TF-IDF, and classifies publications into healthcare subject areas.
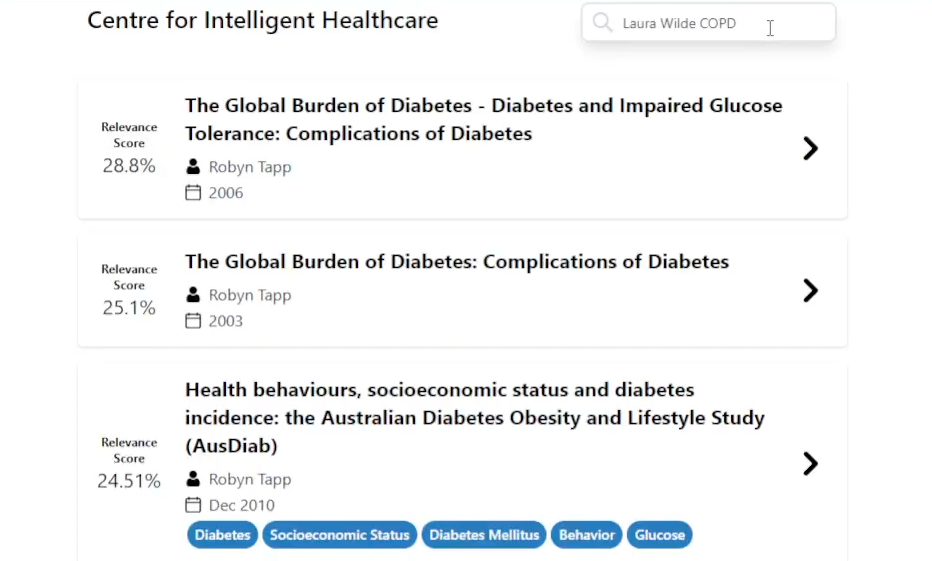
Turning Research Publications into Searchable Knowledge
The Vertical Search Engine connects automated publication metadata extraction with keyword ranking and subject classification. It focuses on RCIH research outputs, giving researchers a dedicated interface for discovering publications within an institutional collection.
The Retrieval Problem
Research discovery requires more than collecting publication pages. Titles, authors, and publication years need a consistent representation, queries need a way to rank relevant records, and subject categories need to make the collection easier to navigate.
The project combines these responsibilities in a workflow that extracts metadata on a weekly schedule, applies text-based relevance ranking, and tags papers by healthcare domain.
From Publication Pages to Search Results
| Stage | Implementation | Purpose |
|---|---|---|
| Collection | Weekly scraping and parsing of RCIH publication outputs | Refreshes the research metadata available to the system. |
| Metadata extraction | Extraction of titles, authors, and publication years | Represents publications as searchable records. |
| Relevance ranking | TF-IDF | Ranks records for keyword-based queries. |
| Subject classification | Automated healthcare-domain tagging | Organizes papers by subject. |
| Search interface | Querying and categorized access | Presents the collection for research discovery. |
Metadata Extraction
The collection pipeline scrapes publication outputs and parses their research metadata. Extracting titles, authors, and publication years gives the retrieval workflow a consistent set of fields to work with, connecting source pages to the records presented in search.
A weekly collection schedule provides a recurring refresh process for the institutional corpus.
Keyword Relevance and Subject Classification
The retrieval implementation includes TF-IDF for relevance ranking. These methods provide text-based approaches to ordering records in response to keyword queries, making ranking an explicit part of the search workflow.
The subject classification module adds healthcare-domain tags to research papers. These categories complement keyword search by organizing publications around their subject matter and supporting categorized access to the collection.
Deliverables and Research Use
The project delivers an automated metadata extraction pipeline, keyword relevance ranking, a subject classification module, and a search interface. The resulting workflow connects source collection with publication discovery: researchers can query institutional outputs and use healthcare subject categories to explore the available research.